2026
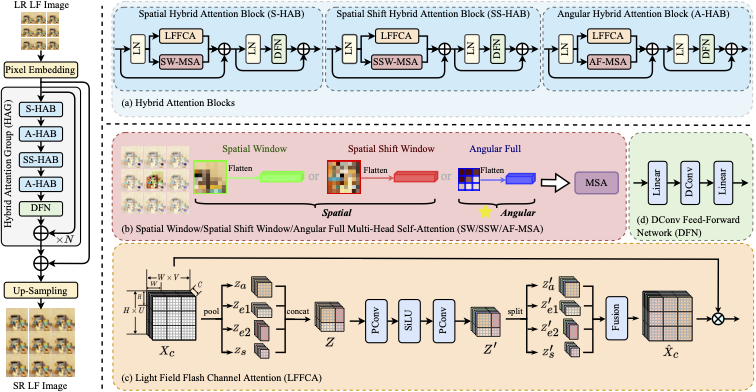
From Nature Image to Light Field: Light Field Super-Resolution with Hybrid Attention Network
Changguang Wu, Jiangxin Dong, Hao Hou, Jinhui Tang
IEEE TMM
We propose a light field hybrid attention network for high-quality light field image super-resolution, which exploits not only the domain-specific information within the spatial/angular domain but also the spatial-angular correlation across domains.
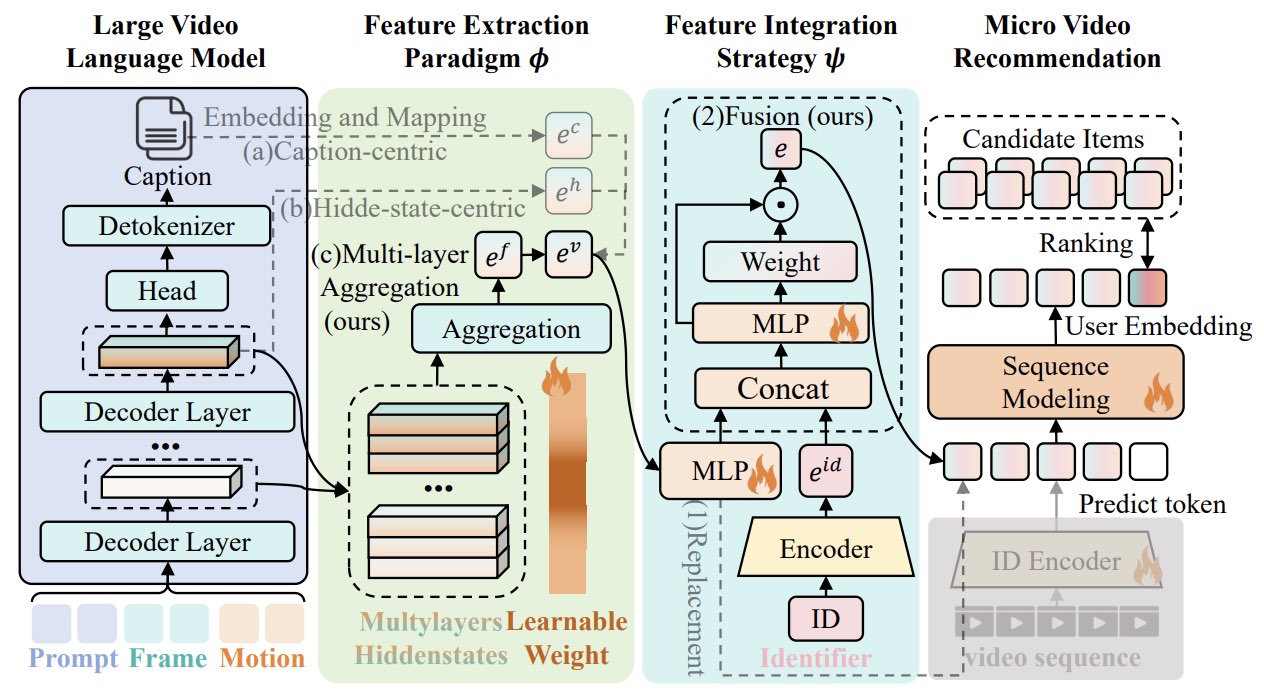
Frozen LVLMs for Micro-Video Recommendation: A Systematic Study of Feature Extraction and Fusion
Huatuan Sun, Yunshan Ma, Changguang Wu, Yanxin Zhang, Pengfei Wang, Xiaoyu Du
ICMR (Best Paper) 2026
We studies frozen LVLM representations for micro-video recommendation and proposes DFF to effectively fuse multi-layer features with ID embeddings.
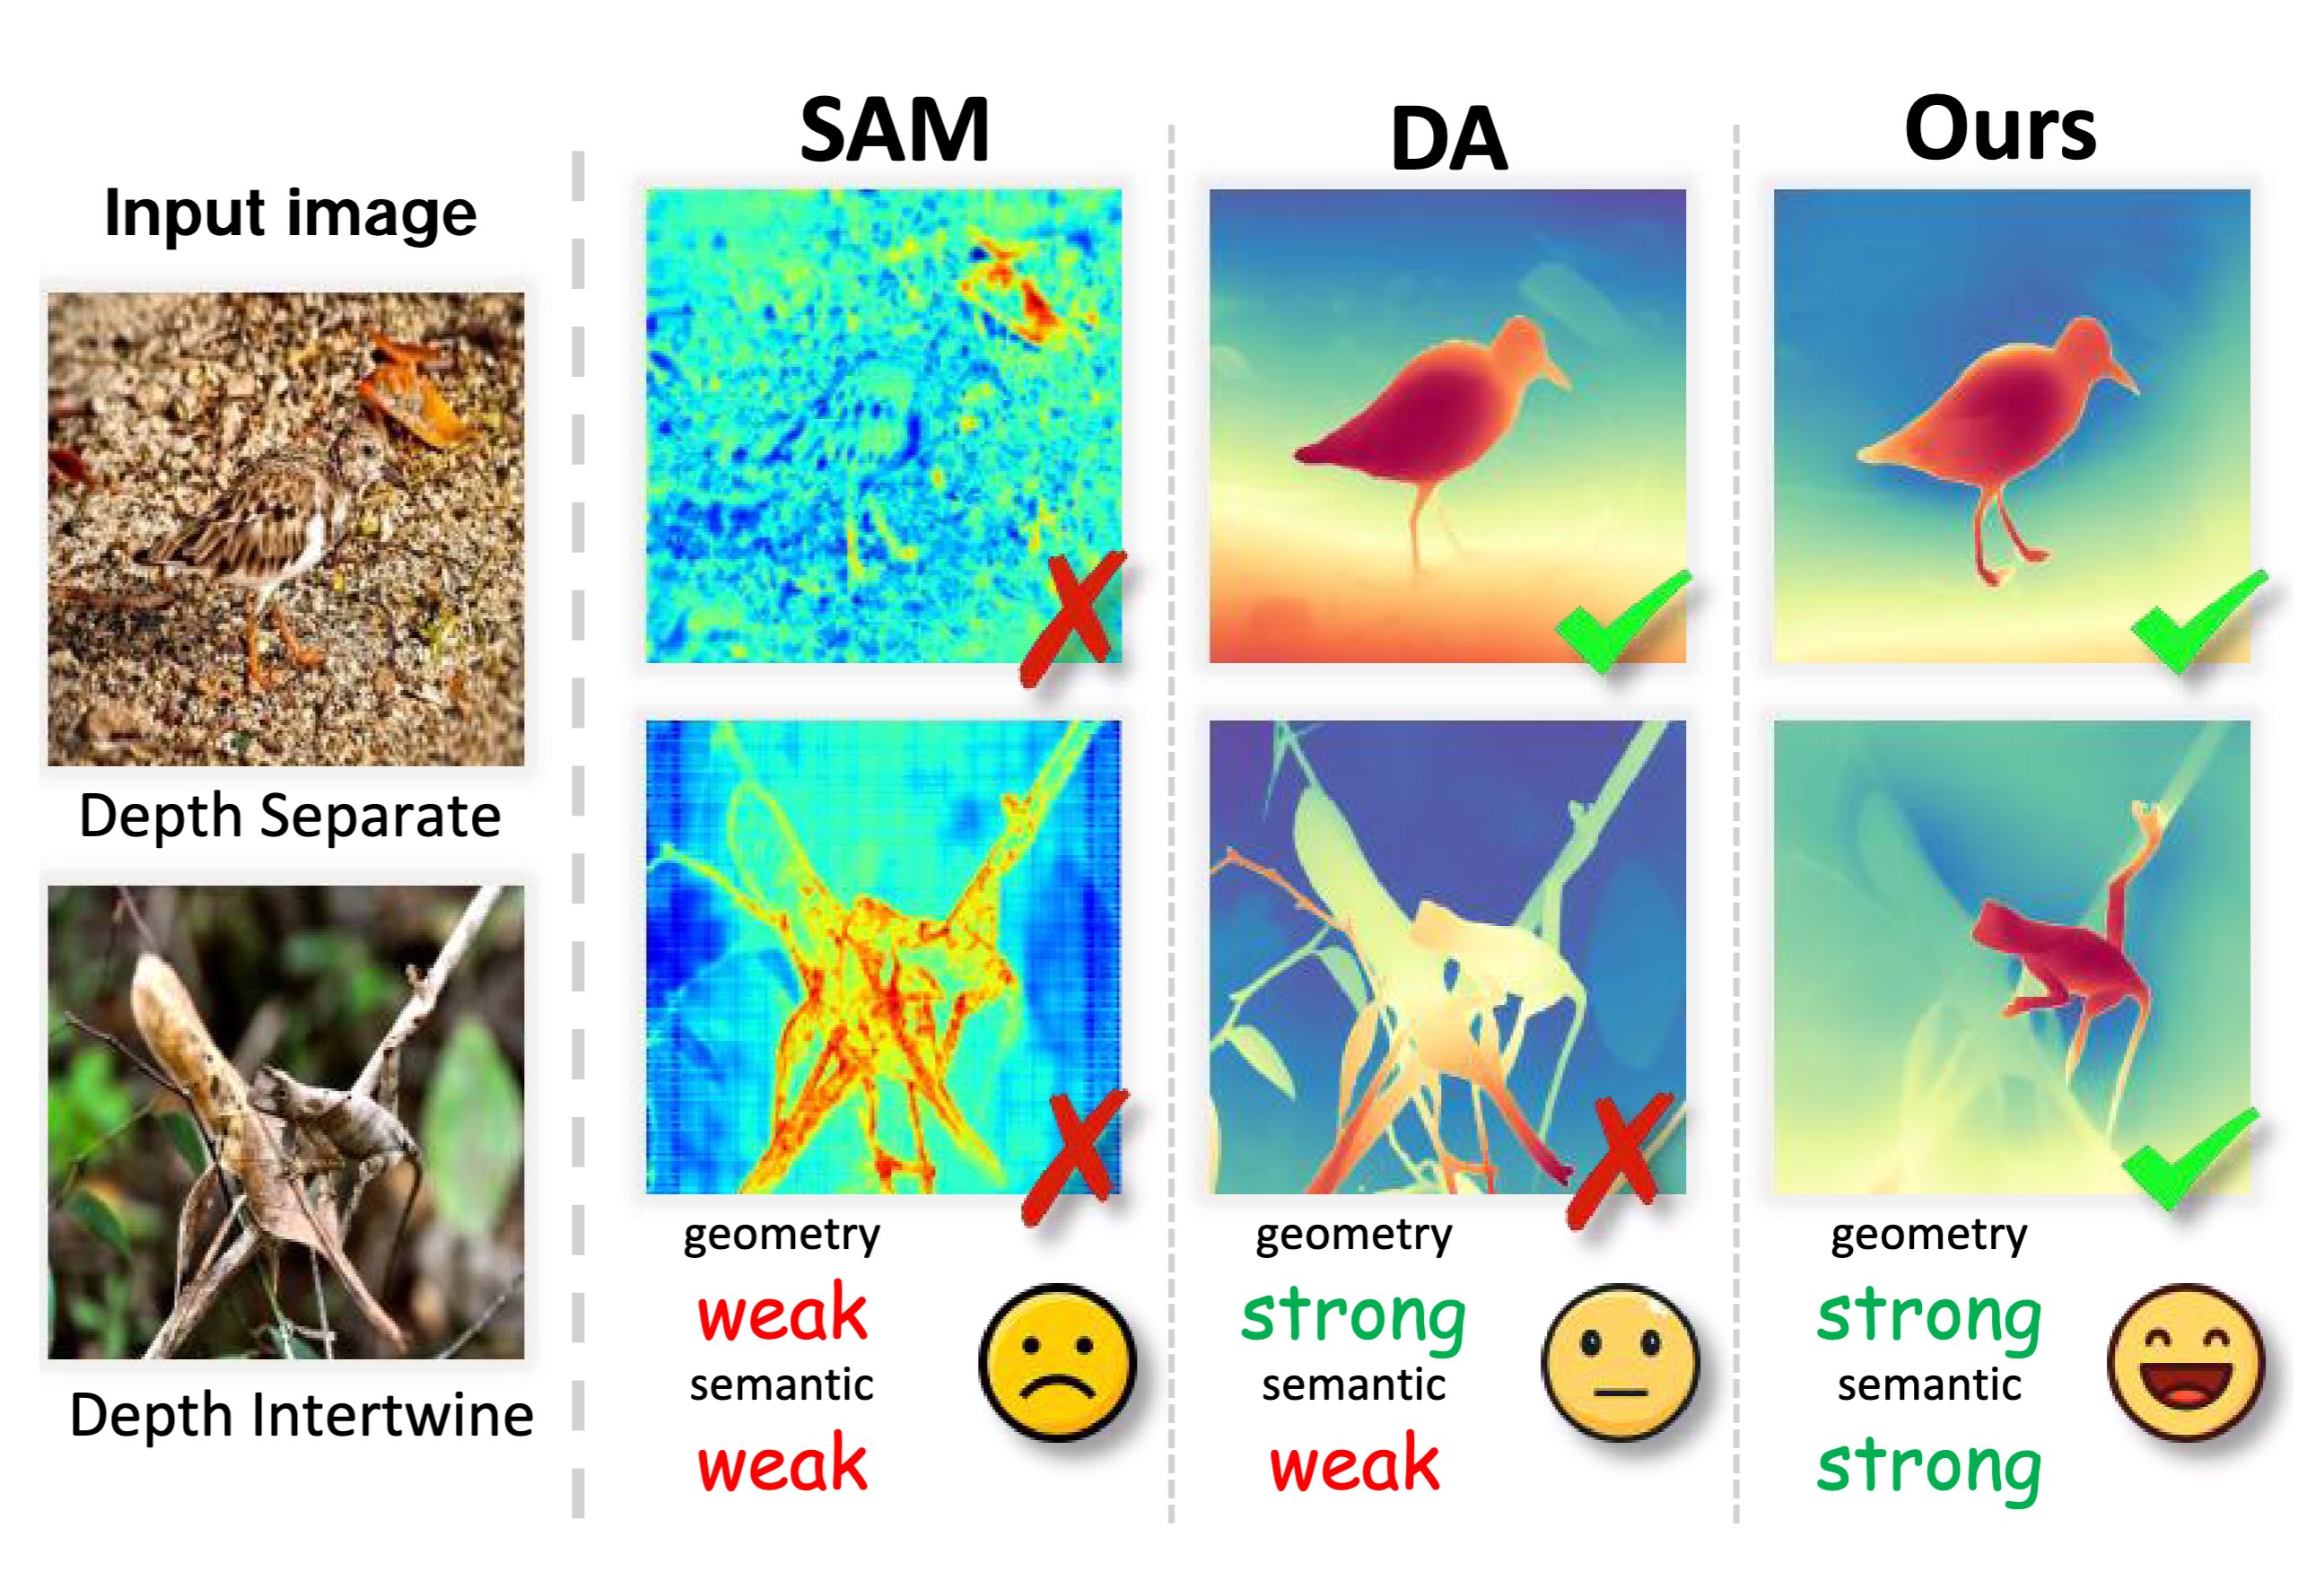
Beyond Appearance: Camouflaged Object Detection via Geometric Structure
jinyu Han, Changguang Wu, Fuming Sun, Jinhui Tang
CVPR 2026
We propose the Depth Segment Anything Model (DepthSAM), a MDE-adapted method for camouflaged object detection (COD).
Beyond Appearance: Camouflaged Object Detection via Geometric Structure
jinyu Han, Changguang Wu, Fuming Sun, Jinhui Tang
CVPR 2026
We propose the Depth Segment Anything Model (DepthSAM), a MDE-adapted method for camouflaged object detection (COD).
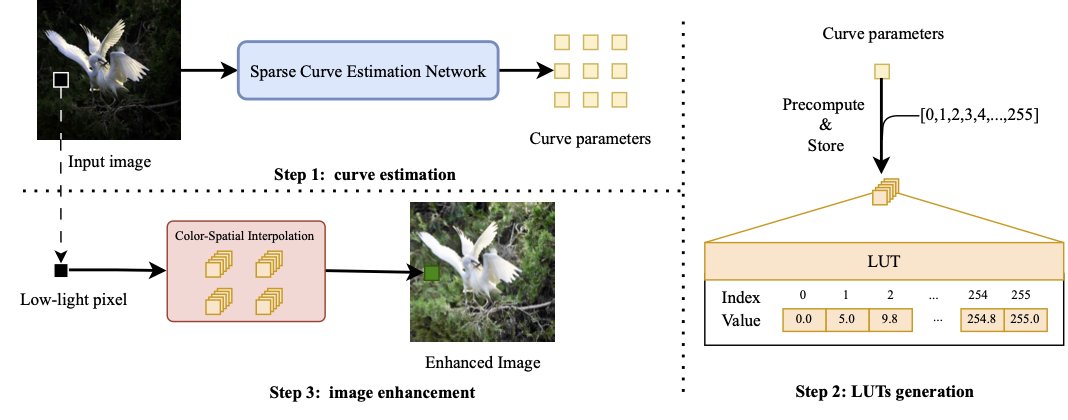
Sparse Curve Estimation for Real-Time Low-Light Ultra-High-Definition Image Enhancement
Changguang Wu, Jiangxin Dong, Hao Hou, Jinhui Tang
IEEE TCSVT 2026
We present an effective and efficient approach for low-light image enhancement, named Sparse Curve Estimation (SCE).
Sparse Curve Estimation for Real-Time Low-Light Ultra-High-Definition Image Enhancement
Changguang Wu, Jiangxin Dong, Hao Hou, Jinhui Tang
IEEE TCSVT 2026
We present an effective and efficient approach for low-light image enhancement, named Sparse Curve Estimation (SCE).
2025
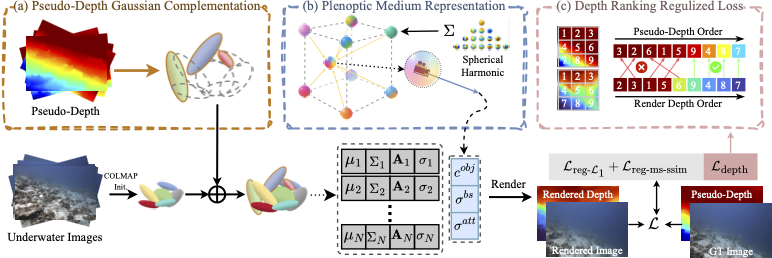
Plenodium: UnderWater 3D Scene Reconstruction with Plenoptic Medium Representation
Changguang Wu, Jiangxin Dong, Chengjian Li, Jinhui Tang
NeurIPS 2025
We present Plenodium (plenoptic medium), an effective and efficient 3D representation framework capable of jointly modeling both objects and participating media.
2024
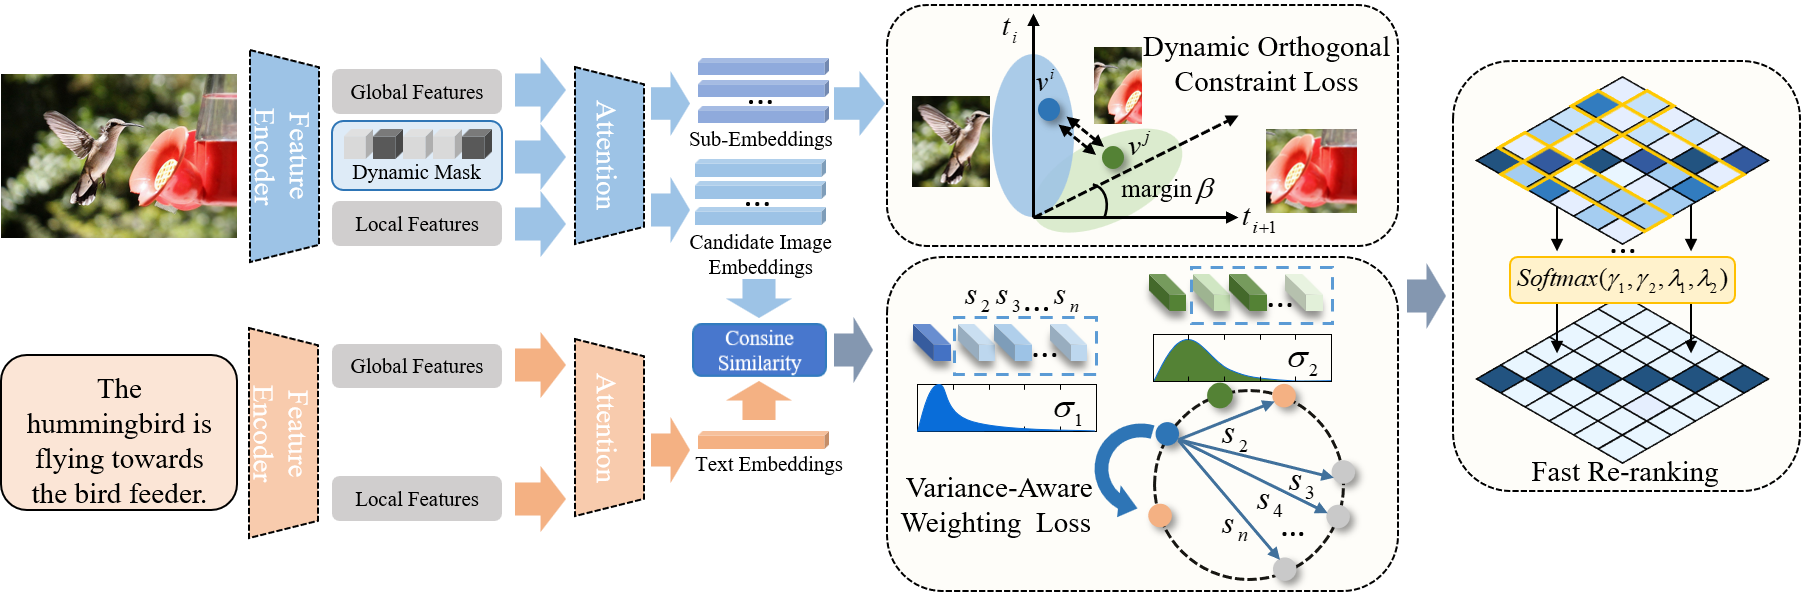
Dynamic Visual Semantic Sub-Embeddings and Fast Re-Ranking
Wenzhang Wei, Zhipeng Gui, Changguang Wu, Anqi Zhao, Dehua Peng, Huayi Wu
IEEE TMM 2024
In this work, we propose a Dynamic Visual Semantic Sub-Embeddings framework (DVSE) to reduce the information entropy.
Dynamic Visual Semantic Sub-Embeddings and Fast Re-Ranking
Wenzhang Wei, Zhipeng Gui, Changguang Wu, Anqi Zhao, Dehua Peng, Huayi Wu
IEEE TMM 2024
In this work, we propose a Dynamic Visual Semantic Sub-Embeddings framework (DVSE) to reduce the information entropy.